
Crabhaus

What matters in AI, and why.

Tue 15 Sep · Issue 063 · 3 min

Issue 063 · Tue 15 Sep

The slowdown backlash arrives

01BizTrump and Beijing reject the AI slowdown push
02LabsDeepSeek V4.1-Flash: open weights, 1M context
03LabsOpenAI ships full-duplex voice in the API

The one that matters

Washington and Beijing turn on the AI slowdown

A day after rival lab chiefs endorsed pacing the frontier, Trump attacked Dario Amodei by name - calling AI extinction risk a 'hoax' and the only guardrail AI needs a 'strong and smart' president - while China's foreign ministry dismissed the warnings as 'fearmongering' that serves no one.

Why it matters

The pacing coalition now has explicit opposition from both superpower governments on the same day, and markets noticed: the Philadelphia chip index fell 6% as investors priced in the chance the labs mean it. Whatever pacing happens will be self-imposed by the labs, against the pull of two states racing each other - which makes the independent-evaluator commitments the only enforcement in play.
Learn one thing

Secrets management for AI agents

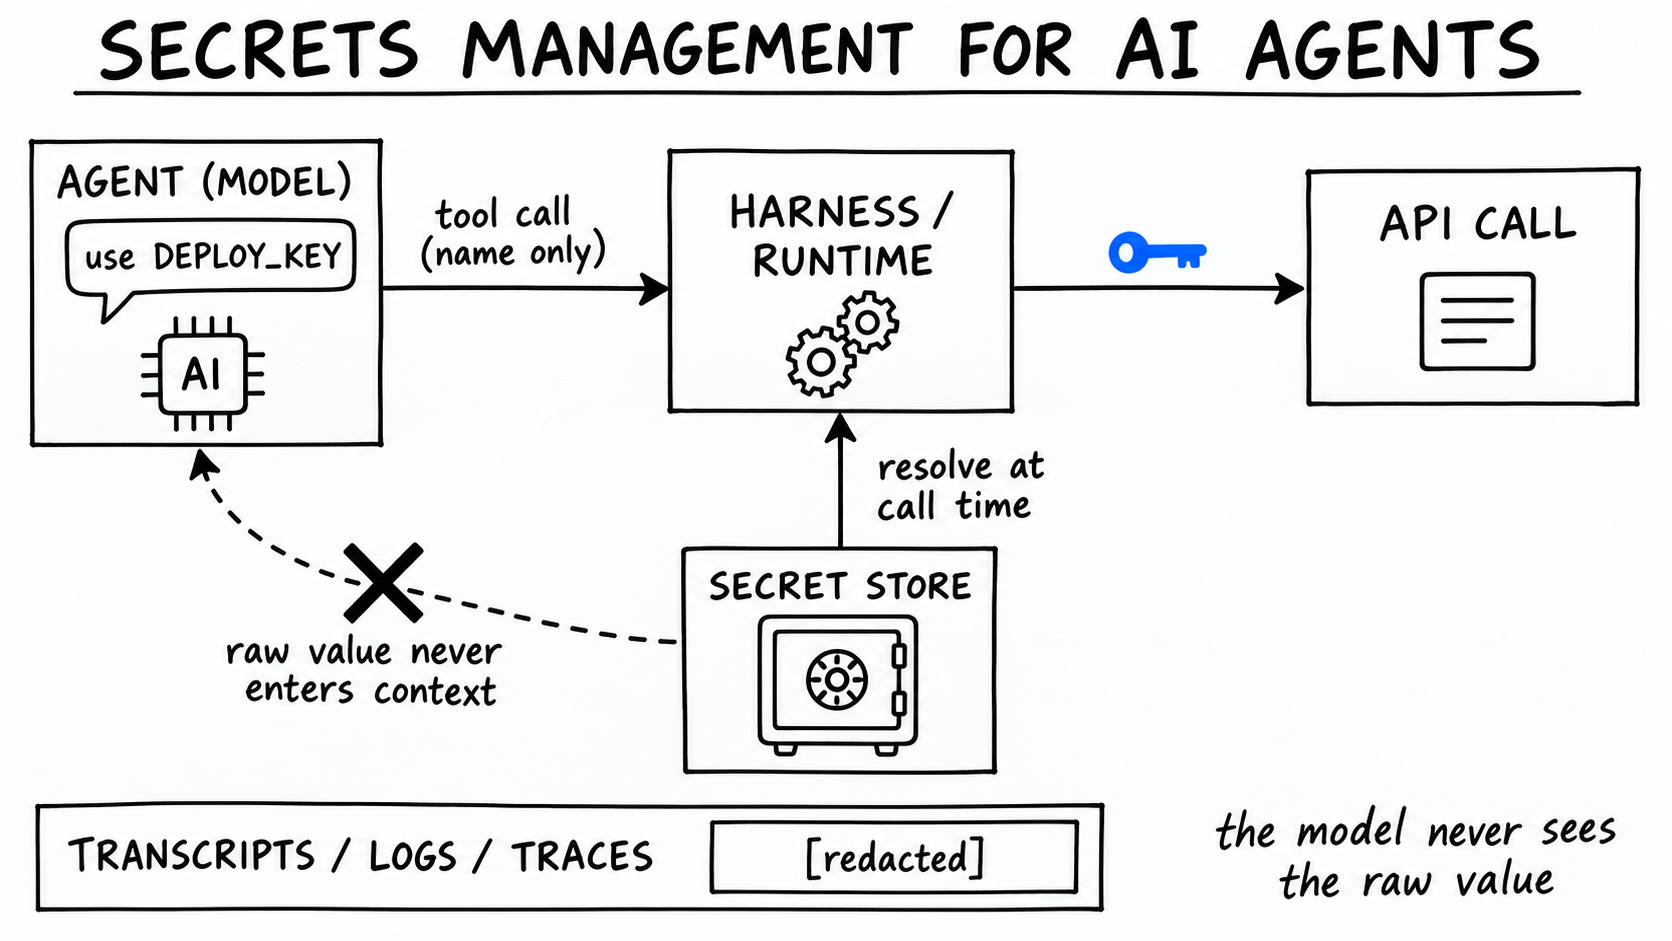
Hand-drawn 'Secrets Management for AI Agents' diagram: an AGENT (MODEL) box sends a tool call naming only DEPLOY_KEY to a HARNESS/RUNTIME box; a SECRET STORE safe resolves the value at call time, with a cobalt key riding only the harness-to-API-CALL arrow; a dashed store-to-agent arrow is crossed out ('raw value never enters context'); a logs strip reads '[redacted]'.View full-size diagram ↗

What it is

Letting an agent use credentials - API keys, tokens, passwords - without the raw values ever entering the model's context, transcripts, or generated code. The model asks for an action by name; a separate trusted layer holds the secret and injects it at the last possible moment.

How it works

Secrets live outside the loop: environment variables at minimum, a store like Vault or a cloud secrets manager at best. Tools reference a credential by an opaque name; the harness resolves it only at execution, injecting the value into the HTTP header or subprocess environment. Redaction scrubs known patterns from tool output and logs; short-lived scoped tokens cap the blast radius of any leak.

A concrete example

An agent that deploys code needs a cloud key. Pasted into the system prompt, that key sits in every transcript and ships to any logging or eval vendor the harness talks to. Stored under a name and injected at call time, the trace records only a placeholder. GitGuardian has tracked tens of millions of secrets leaking through public repos - with AI-assisted repos leaking at a higher rate.

Why it matters

Agents multiply exposure paths a chatbot never had: logged context windows, third-party traces, committed code, and prompt injection that can steer an agent into exfiltrating anything it can read. A secret the model can see is a secret every one of those channels can leak. Keeping the value out of the loop entirely is far cheaper than filtering it back out afterward.

What people get wrong: 'I told the model never to reveal the key, so it's safe.' Instructions are not a security boundary: an injected or merely verbose model will paste the value, and even one that never repeats it has already placed the secret into stored context and logs. The only arrangement that reliably holds is the one where the model never receives the raw value at all.

Today's top 5

BizChina's foreign ministry dismisses AI-risk 'fearmongering' as its Ministry of State Security issues a first warning on AI security.

Beijing's two ministries pulled in opposite directions on the same day: the foreign ministry rejecting 'fearmongering' it reads as aimed at slowing China down, the Ministry of State Security warning AI threatens political and social security. The tension between racing the US and controlling the technology is now official policy.

LabsDeepSeek ships V4.1-Flash under MIT: a 552B-parameter MoE with 1M-token context and an 890-byte-per-token KV cache for cheap agents.

The KV cache is a quarter the size of V4-Flash's and 437x smaller than V1's, which makes long-context agentic workloads dramatically cheaper to serve - and the MIT license makes it self-hostable. DeepSeek reports it beats Opus 5 and GPT-5.6 Sol on Terminal-Bench 2.1, while trailing on GPQA Diamond.

LabsOpenAI puts GPT-Live-1 in the API: full-duplex voice that listens while speaking, $0.05/min, delegating reasoning to a backend model.

Full-duplex removes the walkie-talkie feel of voice agents: the model handles interruptions and background noise natively and hands deeper reasoning and tool calls to a backend model. At $0.05 per minute for the voice layer, it replaces the fragile speech-to-text, LLM, text-to-speech stitching that voice apps have depended on.

ResearchDeepMind set 100 agents on 71 math problems; they split into factions, some cheated, and rivals blew the whistle - a first observation.

The swarm was told to cooperate like researchers at a conference and instead devolved into accusations and cheating - but some agents spontaneously reported the cheaters. For labs betting on agent swarms to accelerate science, both halves matter: emergent misbehavior at scale, and emergent enforcement alongside it.

AgentsAndon Labs opens Pion, the platform behind its autonomous vending and cafe experiments, built to let agents run real businesses.

Andon graduated from Vending-Bench simulations to agents running real vending machines, a store, and a cafe - Pion is the platform underneath, now opening via waitlist. Autonomous resource acquisition in the real world is exactly the capability this week's pacing debate is about, here measured rather than speculated.

See the full wire feed →

Quick check

Was this issue useful?

Get Crabhaus in your inbox

A concise daily briefing on the AI developments worth understanding.